It is an intuitive assumption that a state-backed command economy would prioritise brute-force aggregate capacity over unit economics and power efficiency. The reality on the Chinese mainland is the opposite. Because Beijing’s computing infrastructure is state-guided, power efficiency and unit economics are enforced with a level of hyper-rigid, punitive discipline that Western hyperscalers rarely face. The fundamental problem is that the People’s Republic cannot afford to be wasteful. US export controls have left domestic operators working with lower-yield silicon that consumes more power per FLOP than Nvidia’s latest chips, and an unconstrained build at any cost would collapse the grid before it ever trained a frontier model.
The mainland’s response has been to treat efficiency not as a commercial luxury but as a hard engineering boundary, codified into law and enforced at the level of zoning permits, grid hookups, and provincial expansion approvals. Four interlocking mandates now govern almost every gigawatt of Chinese AI compute, and together they produce a posture that the West, for all its talk of green data centres, has never seriously attempted.
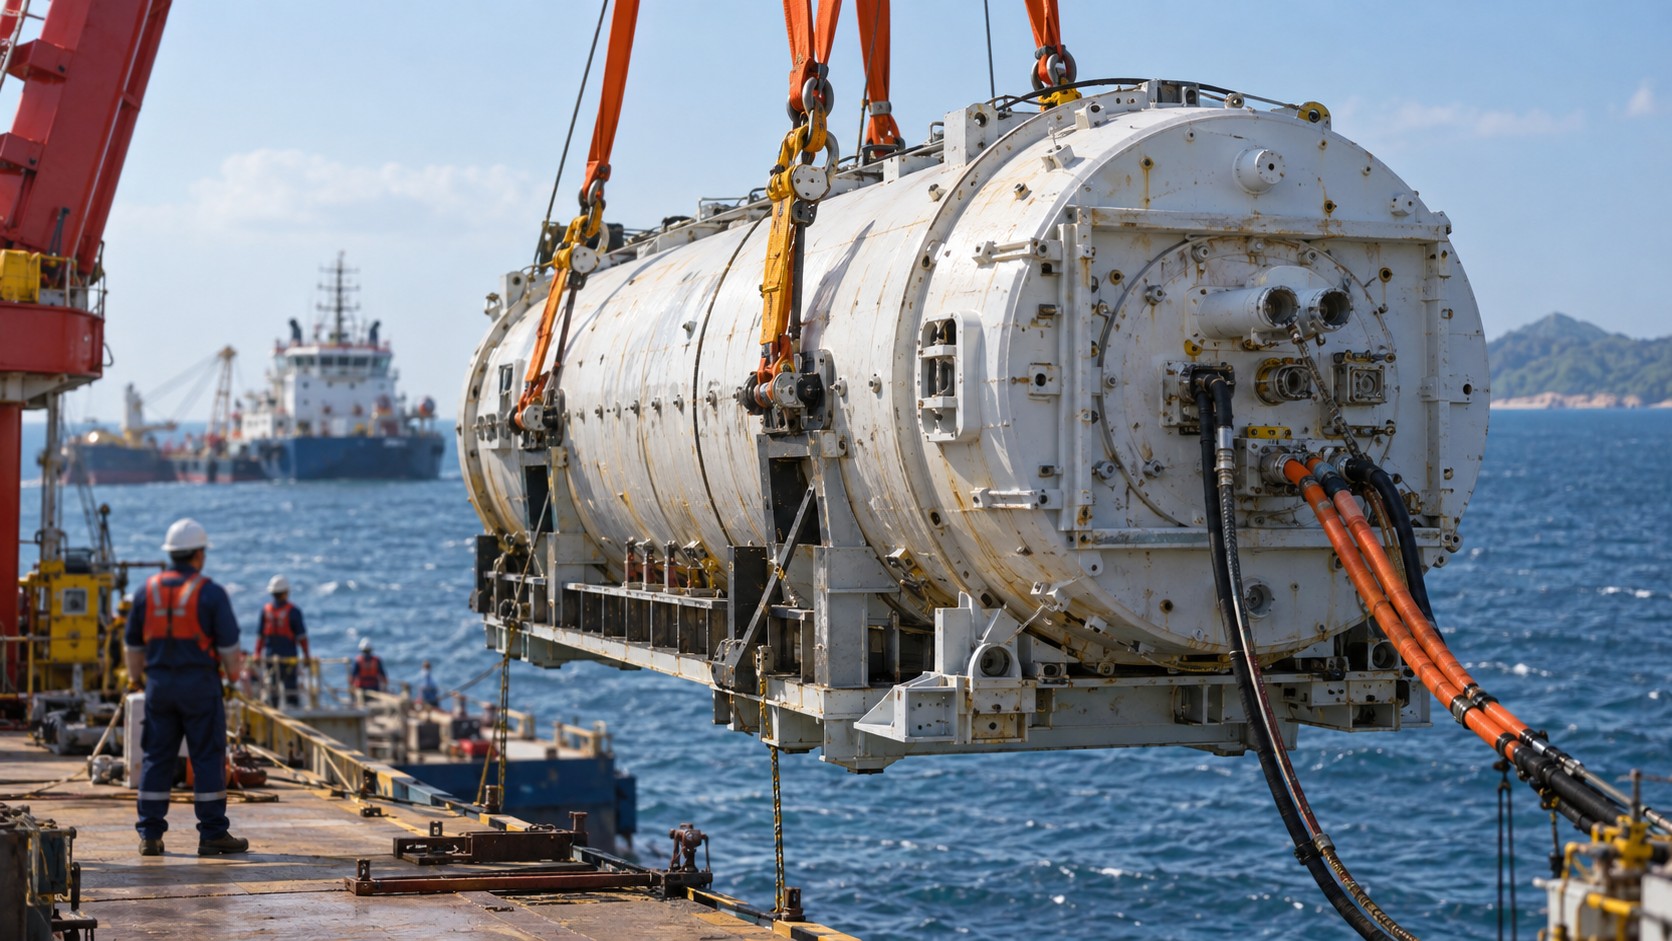
1. Hard PUE caps as a license to operate. In the United States, an operator that wishes to build a data centre with a subpar Power Usage Effectiveness rating of 1.4 can generally do so, provided they own the land and pay the utility bill. In China, the same project would be denied permission to exist. Under the Special Action Plan for Green and Low-carbon Development of Data Centres, jointly issued by the National Development and Reform Commission, the Ministry of Industry and Information Technology, the National Data Bureau, and the National Energy Administration, large and extra-large data centres must reach a PUE of 1.25 or lower by the end of 2025, and the national fleet average must fall below 1.5. Inside the eight designated national computing hubs of the East Data, West Computing fabric, the cap is tighter still, at 1.20 or lower. Municipalities deny zoning, fibre interconnects, and grid access to projects that fail these metrics, which forces operators into extreme engineering. Shenzhen HiCloud now runs a commercial subsea data cabin off the coast of Lingshui County in Hainan, with servers housed in a 1,300-tonne pressure module thirty-five metres below the surface, where ambient seawater eliminates the forty to sixty percent power penalty traditionally spent on air conditioning. A larger twenty-four megawatt subsea facility has just come online in Shanghai’s Lin-gang Special Area, drawing roughly ninety-five percent of its electricity from offshore wind.
2. A 60 percent minimum utilisation floor. In a pure market economy, an operator can over-provision hardware and let clusters idle at fifteen or twenty percent of nameplate capacity while waiting for future workloads, accepting the burned capital as the cost of being early. China’s MIIT explicitly outlaws that posture. National mandates introduced in 2024 require state-backed and major enterprise data centre clusters to maintain a minimum nationwide capacity utilisation rate of sixty percent. The current baseline sits closer to twenty to thirty percent, which is precisely why the rule is being enforced through approval gating. If a regional hub falls below the threshold, Beijing halts approvals for further expansion in that province, freezing developers out of any new pad until existing silicon is saturated. To make the target reachable, MIIT is building a centralised cloud platform to aggregate spare compute and resell it nationally through the East Data, West Computing fabric, dynamically shifting workloads between hubs so that the physical silicon is kept under load. The political logic is austere. An idle GPU is wasted national wealth, and waste at scale is what the constraint regime exists to prevent.
3. The 80 percent renewable sourcing rule. Rystad Energy projects that the Chinese data centre installed base will surpass sixty gigawatts by 2030, up from roughly thirty-two gigawatts at the end of 2025, with annual sector consumption climbing toward two hundred and eighty-nine terawatt-hours and accounting for around 2.3 percent of national electricity demand. Left unregulated, that growth would default to the cheapest available marginal generation, which in much of the country still means coal. To prevent this, the action plan now requires all new data centre projects inside the eight national computing hubs to source at least eighty percent of their electricity from renewables, a higher obligation than even China’s heavy industrial sectors face. The policy has converted western hubs such as Ulanqab in Inner Mongolia into state-of-the-art energy microgrids. The Zhongjin computing base at Ulanqab is physically tethered to two hundred megawatts of dedicated wind capacity, one hundred megawatts of solar, and a forty-five megawatt battery storage system rated at one hundred and eighty megawatt-hours, making it one of the first near-zero-carbon computing complexes in the country. The strategic effect is that AI training is structurally prevented from cannibalising the primary civil electricity grid, even as 21Vianet, Huawei, and ByteDance scale roughly ten gigawatts of further projects in the same region.
4. Algorithmic compression as industrial policy. Because Chinese infrastructure cannot rely on a limitless supply of dense, highly efficient merchant silicon at the Blackwell tier, the country’s entire unit-economic strategy has shifted from hardware scaling toward algorithmic compression. The shockwaves that DeepSeek V3 and R1 sent through Western capital markets are the direct intellectual product of that constraint. DeepSeek’s six hundred and seventy-one billion parameter Mixture-of-Experts model activates only thirty-seven billion parameters per token and uses Multi-Head Latent Attention to compress the inference key-value cache into a shared low-rank representation. Reported full training cost is roughly 2.788 million H800 GPU-hours, a fraction of what a comparable dense Western frontier model consumes. When the compute pool is structurally throttled by geopolitics, the labs that survive are the ones that invent architectures which extract more capability per FLOP. The state’s role in this is indirect but decisive. It does not write the model code. It simply makes wasteful training economically and politically untenable, and the market for compressed architectures follows.
5. The strategic implication for the West. The dominant assumption inside American capital allocation is that export controls have permanently degraded China’s AI trajectory by capping the ceiling of available compute. That framing misses the second-order effect. By forcing the mainland to optimise every layer of the stack, from cooling medium and rack density up through attention mechanism and quantisation regime, the controls have produced a competitor that operates closer to thermodynamic and information-theoretic limits than its US counterparts. Western hyperscalers can still out-spend China at the frontier of raw nameplate capacity, particularly through the GB200 and GB300 generations now ramping into US sites. They cannot easily out-discipline a system in which inefficiency is illegal. As American data centre power demand collides with the physical limits of what new transmission and generation can deliver inside a five-year window, the productivity gap between gigawatts spent and useful tokens produced is becoming the actual battleground, and on that axis Beijing has spent four years building structural advantage.
The Verdict. China is not building a chaotic, cost-is-no-object AI infrastructure bubble. It is building a highly regulated, highly constrained national compute utility, governed by hard caps on energy intensity, minimum utilisation floors, renewable sourcing requirements, and an industrial bias toward algorithmic compression. The mainland’s planners have internalised the lesson that when a country has a structural hardware deficit, wasting a single watt of power or a single GPU cycle is a national security failure. The Western response cannot be more spending alone. It will require the rediscovery of unit economics, efficiency mandates with genuine enforcement teeth, and a clear-eyed acceptance that AI compute is no longer a commercial luxury but a strategic utility, to be governed accordingly.
Read our full Report Disclaimer.
Important Notice
Bretalon Ltd is not a registered investment adviser or broker-dealer. This report is published free of charge as impersonal, general commentary in a publication of regular circulation. It is not investment, financial, legal, or tax advice, and not an offer or recommendation to buy, sell, or hold any security; no report recommends, rates, or values any specific security. Do not rely on it for investment or business decisions; always consult a qualified professional. It speaks only as of its publication date, and its views on companies, securities, and markets are analytical opinion, not fact. As of 22 October 2026, neither Bretalon Ltd nor those involved in its reports have ever been paid by any company a report discusses (unless expressly disclosed in the report). Those involved hold no direct positions in individual securities and hold any securities only through mutual funds and similar pooled or collective investment funds. Bretalon Ltd provides strategic advisory services to publicly listed and privately held companies under separate written agreements. This report was drafted with AI from public sources, its illustration is AI-generated, and it was approved for publication by a person acting for Bretalon Ltd. Provided "as is" without any duty of care to readers. Read our full Report Disclaimer.